
Codex vs Claude Code now comes down to accuracy against price. Claude Code defaults to Claude Opus 5.5 on Pro, Max, Team, Enterprise, and the API, and on the official Terminal-Bench 4.0 leaderboard it scores 64.85% against 58.18% for Codex running GPT-6.1 Sol. Opus 5.5 also tops vals.ai's Terminal-Bench 2.1 run at 87.64%, with GPT-6 Astra at 87.27%. Codex is cheaper. GPT-6.1 Sol costs $2/$10 per million tokens against $4/$20 for Opus 5.5, and on DeepSWE GPT-6 Astra resolves 74% of tasks at $4.43 each, the same rate Claude Opus 5 reaches at $11.84. Plans start at $20 on both sides. ChatGPT Plus publishes its limits (15-160 GPT-6.1 Sol messages per five hours) and Codex Pro ($100, $200, $500) has no five-hour cap. Claude Max costs $100 or $200 and publishes no message counts. Pick Claude Code for the highest benchmark scores and coordinated agent teams. Pick Codex for cost per task and open-source tooling.
Want the cheapest resolved ticket? Codex: GPT-6.1 Sol at $2/$10 per million tokens, GPT-6 Astra at $4.43 per DeepSWE task, and Pro plans with no five-hour limit. Want the highest scores in large, messy repos? Claude Code: Opus 5.5 leads Terminal-Bench 4.0 (64.85% vs 58.18%) and SWE-bench Pro (89.9% on llm-stats), and Agent Teams track dependencies between subtasks. Run both $20 plans before paying for either $100 tier.
Summary
Both tools changed default models again in the fall. Claude Code moved its default to Claude Opus 5.5 in v2.1.280 (Sonnet 5 had been the Pro and Team Standard default, Opus 5 everywhere else). Codex made GPT-6.1 Sol its recommended model, kept GPT-6 Astra for the hardest work, and retired GPT-5.5 for ChatGPT sign-in on October 14. On the official Terminal-Bench 4.0 board Claude Code with Opus 5.5 scores 64.85% and Codex with GPT-6.1 Sol or GPT-6 Astra scores 58.18%. Codex answers with price: GPT-6.1 Sol costs half as much per token as Opus 5.5. The real question is still the same: isolated speed (Codex) or coordinated depth (Claude), and what that costs in tokens.
What Is Claude Code and What Is Codex CLI
Claude Code is Anthropic's coding agent. It runs Claude models (Opus 5.5 by default, plus Sonnet 5.5, Haiku 5.5, and Fable 5.1) in the terminal, the desktop app, VS Code, and cloud sessions, and it is proprietary. Codex is OpenAI's coding agent. The CLI is open source under Apache-2.0 and written in Rust, and the same agent runs in the ChatGPT desktop app, the IDE extension, and the web. Both read a project instruction file (CLAUDE.md for Claude Code, AGENTS.md for Codex), both support MCP servers and plugins, and both are included in a $20 monthly plan.
| Dimension | OpenAI Codex (GPT-6.1 Sol) | Claude Code (Opus 5.5) |
|---|---|---|
| Terminal-Bench 4.0 (tbench.ai, agent + model) | 58.18% (GPT-6.1 Sol and GPT-6 Astra) | 64.85% (Opus 5.5) |
| Terminal-Bench 2.1 (vals.ai, Terminus 2) | 87.27% (GPT-6 Astra) | 87.64% (Opus 5.5) |
| SWE-bench Pro (llm-stats vendor aggregate) | 64.6% (GPT-5.6 Sol; no GPT-6 entry yet) | 89.9% (Opus 5.5) |
| SWE-bench Verified (vals.ai, Sep 1) | 96.2% (GPT-5.6 Sol) | 97.0% (Opus 5; no Opus 5.5 entry yet) |
| DeepSWE (Sep 22, shared harness) | 74% at $4.43/task (GPT-6 Astra) | 74% at $11.84/task (Opus 5) |
| API price per 1M tokens | $2 / $10 (GPT-6.1 Sol) | $4 / $20 (Opus 5.5) |
| Context window | 1,050,000 tokens (922K max input), 128K output | 1M tokens, 128K output |
| Multi-agent model | Subagents GA, configurable thread cap | Agent Teams + fork subagents |
| $20/mo limits | Plus: 15-160 GPT-6.1 Sol messages per 5 hours, published | Pro: unpublished caps |
| Open source | Apache-2.0, ~130K stars | Proprietary, ~152K stars |
| Current default model | GPT-6.1 Sol recommended (GPT-5.5 retired Oct 14) | Opus 5.5 (since v2.1.280) |
| Latest release | v0.163.0 (October 15, 2026) | v2.1.303 (October 18, 2026) |
SWE-bench Pro Accuracy (October 2026)
Claude leads on Pro; no GPT-6 model is listed yet
Source: llm-stats SWE-Bench Pro leaderboard, October 19, 2026 (vendor-reported scores).
DeepSWE Resolution Rate (Sep 22, 2026)
Independent, same harness for every model, 113 tasks
Source: deepswe.datacurve.ai v1.1 leaderboard, updated September 22, 2026. Opus 5.5 and GPT-6.1 Sol are not on the board yet.
- Choose Codex if: You want the lowest token price (GPT-6.1 Sol at $2/$10), the cheapest resolved ticket ($4.43 on DeepSWE with GPT-6 Astra), an open-source CLI, or Pro plans with no five-hour limit
- Choose Claude Code if: You want the top Terminal-Bench 4.0 score (64.85% with Opus 5.5), the top SWE-bench Pro score (89.9%), or agent teams with messaging and dependency tracking
- Choose both if: You want Codex for cheap parallel work and Claude Code for complex orchestration; the two $20 plans together cost less than either $100 tier
Terminal-Bench 4.0 on tbench.ai runs each model inside its own agent (Claude Code or Codex), so it compares the tools. vals.ai's Terminal-Bench 2.1 runs every model in the same Terminus 2 harness, so it compares the models. SWE-bench Pro numbers on llm-stats are vendor-reported. The newest models are missing from several boards: vals.ai SWE-bench Verified has no Opus 5.5 entry, llm-stats has no GPT-6 entry, and DeepSWE has neither Opus 5.5 nor GPT-6.1 Sol.
The Architectural Shift
Both tools have GA multi-agent workflows. Codex shipped subagents GA on March 14. The main agent spawns explorer, worker, or custom agents and collects their results, the concurrent thread cap is a config setting (agents.max_concurrent_threads_per_session), and Ultra mode delegates to subagents on its own. Claude Code's Agent Teams share a task list and message each other, sessions can message other sessions (v2.1.220+), and fork subagents became the default in claude -p, the Agent SDK, the desktop app, and VS Code in v2.1.302. Both support goals, memories, hooks, and plugins.
Token Usage: Claude Code vs Codex on Identical Tasks
Claude uses 3-4x more tokens but produces more thorough output
Source: Independent benchmark by community testers, Feb 2026. Claude's higher token count correlates with more deterministic, thorough outputs.
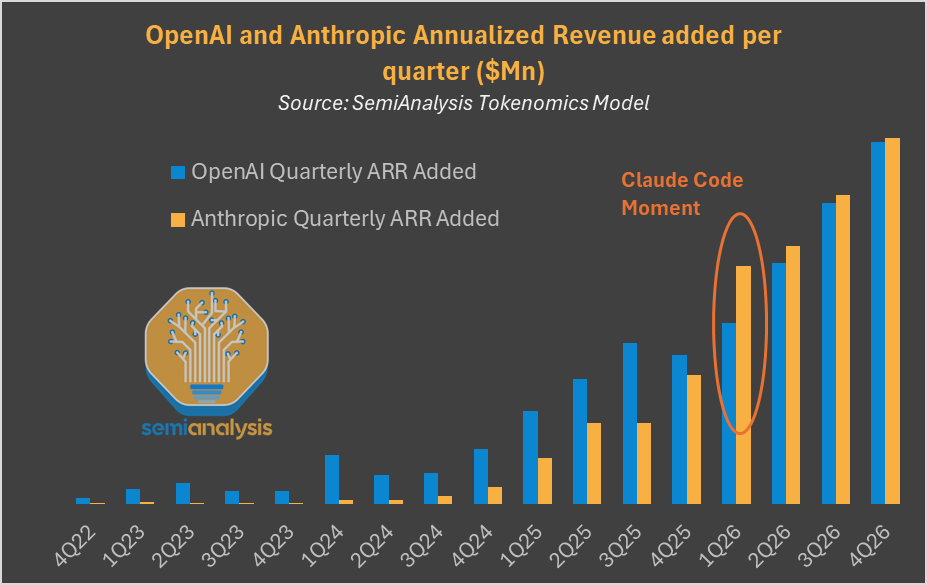
Source: SemiAnalysis Tokenomics Model. Anthropic's quarterly ARR growth accelerated sharply at the "Claude Code Moment" in Q1 2026.
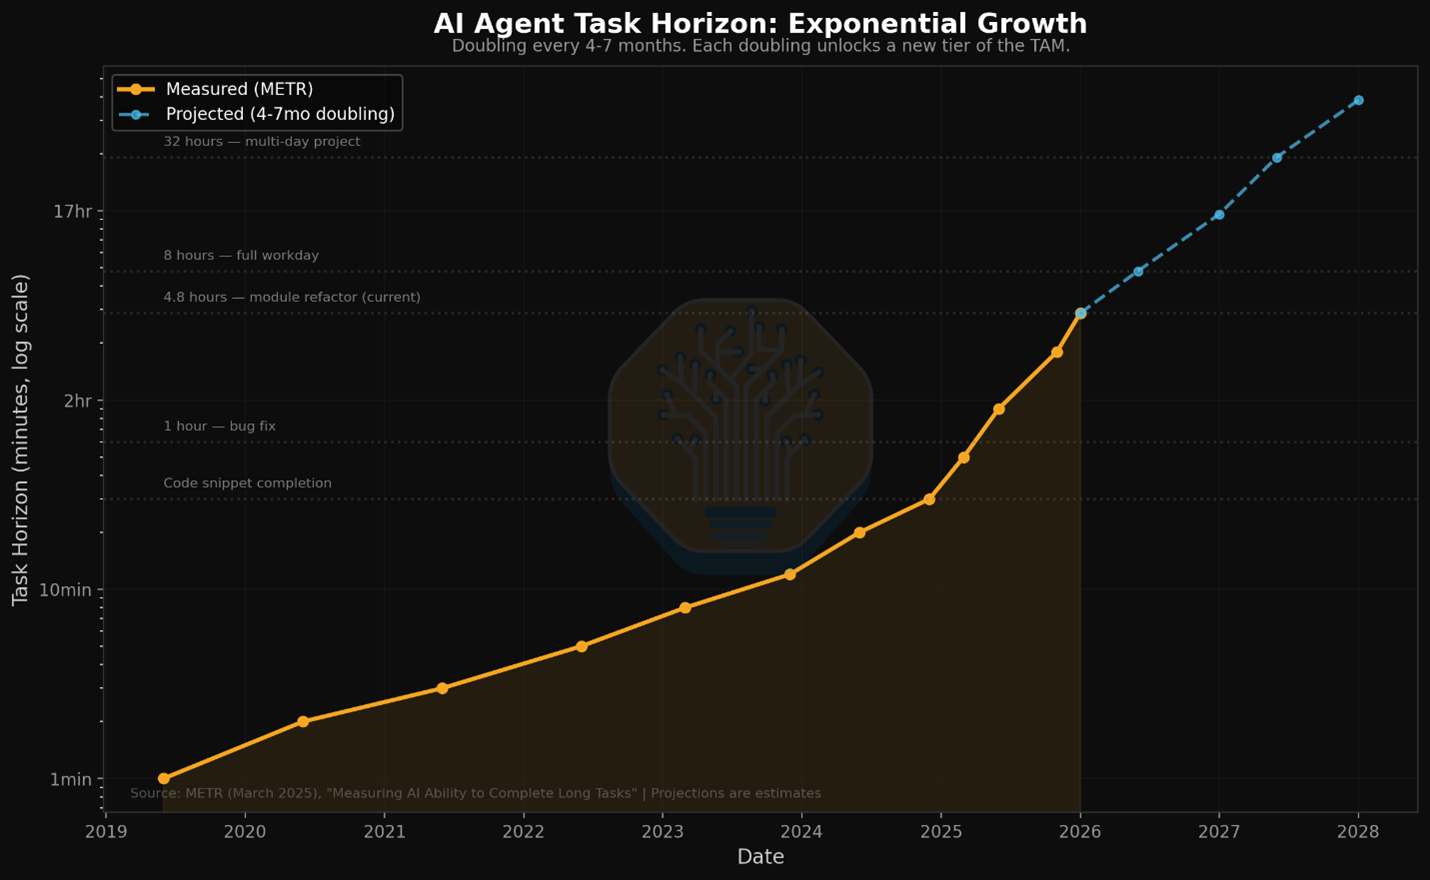
Source: METR / SemiAnalysis. AI agent task horizons are doubling every 4-7 months.
Stat Comparison
Synthetic benchmarks tell part of the story. These 5-bar ratings reflect daily workflow impact across speed, autonomy, consistency, subagent support, and limit generosity.
OpenAI Codex
GPT-6.1 Sol at $2/$10 + parallel subagents
"Maximum velocity with subagents GA and persistent goals."
Claude Code
Opus 5.5 default + agent teams + fork subagents
"Best-in-class subagent coordination with agent view dashboard."
GitHub and Marketplace Stats (October 2026)
Claude Code
- ~152,000 GitHub stars (up from 71.5K in Feb)
- v2.1.303 (October 18, 2026); 2.1.292 on the stable channel
- Opus 5.5 default on Pro, Max, Team, Enterprise, and the API (v2.1.280+)
- Fork subagents on by default in claude -p, the Agent SDK, desktop, and VS Code (v2.1.302)
- Auto mode is the default permission mode since August 14
OpenAI Codex
- ~130,000 GitHub stars (up from 62.4K in Feb)
- v0.163.0 (October 15, 2026)
- Codex App: macOS + Windows, Chrome extension, mobile
- Rust-native CLI; GPT-6.1 Sol recommended, GPT-5.5 retired for ChatGPT sign-in Oct 14
- Subagents GA (March 14) + codex agents dashboard (v0.149.0)
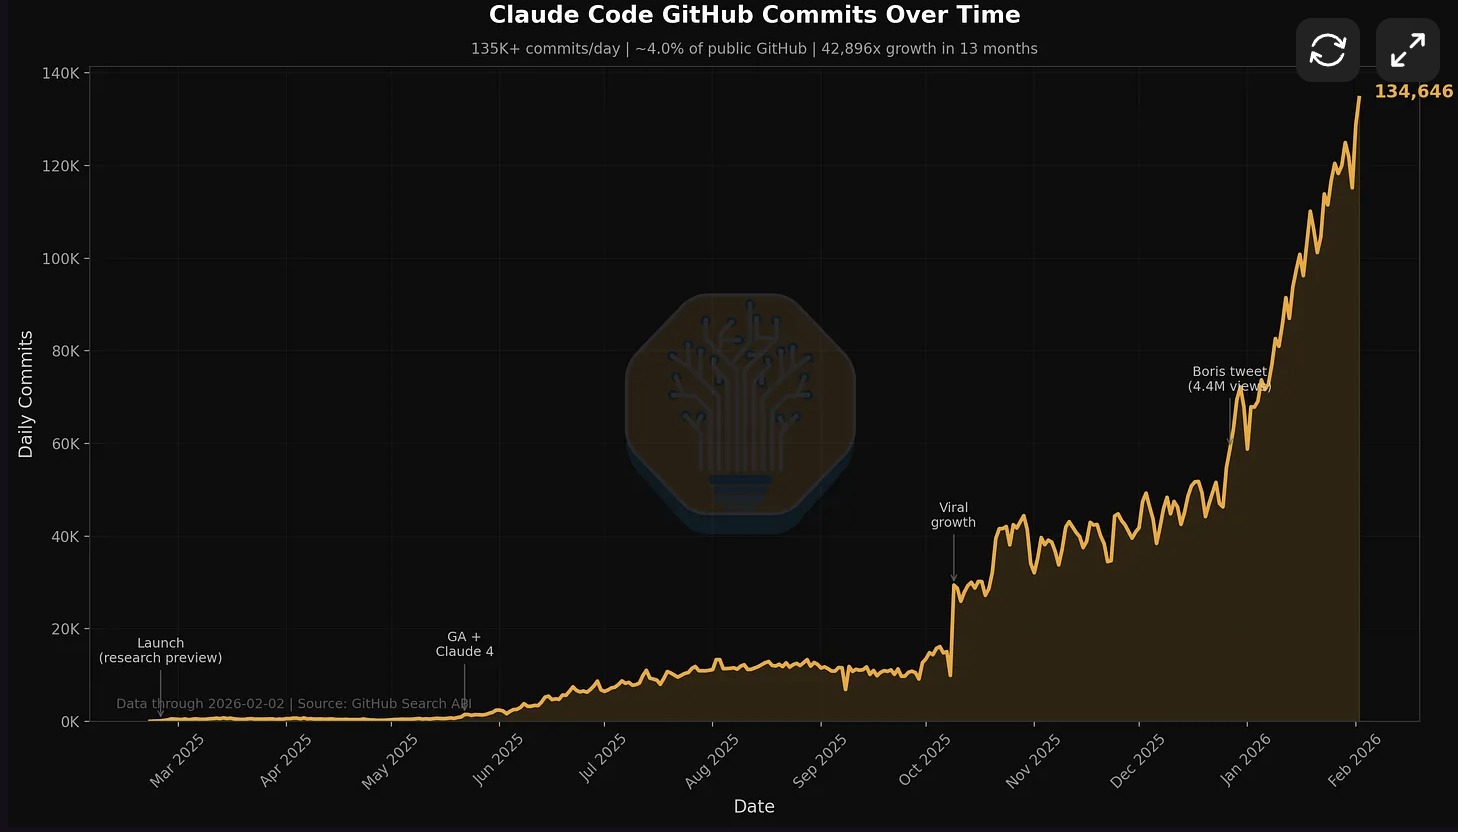
Source: SemiAnalysis / GitHub Search API. Claude Code now accounts for ~10% of all public GitHub commits, up from 4% in February.
Reading the Stats
Codex optimizes for speed and autonomy at the cost of consistency. Claude Code optimizes for consistency and orchestration at the cost of limits. Neither dominates across all dimensions. Both kept shipping through October 2026. Codex moved to the GPT-6 family and added /config search, mid-turn steering, and parallel read-only tools in v0.163.0. Claude Code moved to Opus 5.5 and turned fork subagents on by default.
Subagent Architecture: How Each Tool Isolates Context
Both Codex and Claude Code now have production-ready multi-agent support. Codex shipped subagents to GA on March 14, 2026. Claude Code's Agent Teams added the agent view dashboard (v2.1.139) and, in v2.1.302, fork subagents by default outside the terminal. A dedicated context window per task is now standard in both tools, but they implement it in fundamentally different ways.
Why Subagents Matter
The single biggest limitation of AI coding agents is context window pollution. You ask the agent to refactor authentication, it reads 40 files, and by the time it gets to the last file it has forgotten the patterns from the first. Subagents solve this by giving each subtask its own dedicated context window. The auth refactor agent does not share context with the test-writing agent. Each one focuses.
| Aspect | Codex (October 2026) | Claude Code (October 2026) |
|---|---|---|
| Multi-agent model | Subagents GA: manager + explorer/worker/default agents | Agent Teams: coordinated sub-agents with messaging |
| Isolation model | Cloud sandbox per task (container) | Git worktree per agent (local) |
| Max parallel agents | Configurable (agents.max_concurrent_threads_per_session) | No hard limit (burns limits per agent) |
| Task coordination | Manager decomposes and collects results | Shared task list with dependency tracking |
| Agent communication | Manager collects worker results | Direct messaging + broadcast between agents |
| Persistent goals | /goal: multi-day objectives, pause/resume | /goal: persistent work until condition met |
| Cross-session memory | Memories (configurable, off by default) | Auto-memory (saves project context) |
| Execution environment | Cloud (internet disabled for security) | Local machine (full access) |
Codex: Subagents GA (March 14, 2026)
The main agent decomposes your task and spawns explorer, worker, or custom agents in parallel, then collects their results. The concurrent thread cap is set by agents.max_concurrent_threads_per_session, and Codex picks a default when it is unset. Ultra mode delegates to subagents on its own.
Claude Code: Agent Teams + Agent View
Agent Teams let you spawn sub-agents that share a task list with dependency tracking, send messages to each other, and work in parallel on git worktrees. The new 'claude agents' command (v2.1.139) provides a dashboard to manage all running, blocked, and completed sessions in one view.
Dedicated Context Per Task
Both approaches validate the same insight: a dedicated context window per task is a lasting primitive. The question is whether you want isolated speed (Codex) or coordinated depth (Claude). For greenfield tasks that are independent of each other, Codex's isolation model wins. For complex refactors where subtasks have dependencies, Claude's coordinated teams win.
Claude Code: Agent Teams in Action
# Spawn a team for a complex feature
$ claude "Build the payment integration"

# Claude Code automatically:
# 1. Creates a team with task list
# 2. Spawns researcher agent → explores Stripe SDK patterns
# 3. Spawns implementer agent → writes the code (blocked until research done)
# 4. Spawns test-writer agent → writes tests in parallel
# Each agent has its own context window. No pollution.
# Agents message each other when done: "research complete, found 3 patterns"
# Task dependencies prevent implementer from starting before researcher finishes
Usage Limits: What the Pricing Pages Leave Out
This is the section that will save you hundreds of dollars. The pricing pages don't tell you the real story about limits.
As of October 2026, OpenAI publishes per-model ranges for local Codex messages per five-hour window. ChatGPT Plus gets about 15-160 GPT-6.1 Sol messages, 5-45 GPT-6 Astra, and 350-3,000 GPT-6 Luna, and weekly limits may also apply. Pro plans at $100, $200, and $500 currently have no five-hour limit. Anthropic publishes no message counts: Max is 5x or 20x Pro usage, shared between the Claude apps and Claude Code. At $20, ChatGPT Plus still gets more sessions per dollar than Claude Pro.
| Tier | Codex (ChatGPT) | Claude Code | Key Difference |
|---|---|---|---|
| $0 | Free: GPT-6 Luna in the desktop app (rollout) | Free: chat only, no Claude Code | Codex is the only agent with a $0 tier |
| $8/month | Go: lightweight Codex tasks | N/A | Entry tier for Codex only |
| $20/month | Plus: 15-160 GPT-6.1 Sol / 5-45 Astra / 350-3,000 Luna messages per 5 hours | Pro ($17/mo billed annually): Claude Code included, unpublished caps | Codex publishes its limits and they run looser |
| $100/month | Pro $100: no five-hour limit | Max 5x: 5x Pro usage | Both have $100 tiers |
| $200/month | Pro $200: no five-hour limit | Max 20x: 20x Pro usage | Both generous at this tier |
| $500/month | Pro $500: adds Ultrafast mode | N/A | Codex only |
The Tier Structure in October 2026
OpenAI's ladder is $0 (Free), $8 (Go), $20 (Plus), and Pro at $100, $200, or $500, plus a $20/user Business tier. Anthropic's is $20 (Pro), $100 (Max 5x), and $200 (Max 20x), with Team Standard seats at $20 billed annually or $25 monthly. Both platforms sell additional credits at API rates when you hit limits, and Codex also runs against a plain API key for overflow.
The real cost question in 2026 is not the subscription price, it's how many agent sessions you get. With subagent workflows, each agent team run burns through limits faster because you are running multiple context windows in parallel. Codex caps concurrent subagent threads at a configurable limit. Claude's Agent Teams have no hard cap but eat limits proportionally to the number of sub-agents spawned.
Token Economics Nobody Discusses
A data point that should concern Claude users: in identical benchmark tasks, Claude Code used 4x more tokens than Codex.
| Task | Codex Tokens | Claude Tokens | Ratio |
|---|---|---|---|
| Figma Plugin Build | 1,499,455 | 6,232,242 | 4.2x more |
| Scheduler App | 72,579 | 234,772 | 3.2x more |
| API Integration | ~180,000 | ~650,000 | 3.6x more |
Why Claude Uses More Tokens
Claude's higher token usage is not necessarily waste. It correlates with more thorough, deterministic outputs. Claude "thinks out loud" more, asks clarifying questions, and provides more detailed explanations. Whether this is valuable depends on your use case.
Claude Token Philosophy
More tokens = more context = more thorough. Claude prioritizes completeness over efficiency, which helps with complex refactoring but burns through limits faster.
Codex Token Philosophy
Fewer tokens = faster completion = lower cost. Codex prioritizes efficiency, which means faster results but potentially less thorough coverage of edge cases.
API Pricing Reality (October 2026)
If you are running either agent against the API directly (not the subscription), the current rate cards:
- Claude Opus 5.5: $4 input / $20 output per 1M tokens (Opus 5, now legacy, was $5 / $25)
- Claude Sonnet 5.5: $2 / $10; Haiku 5.5: from $0.10 / $0.50; Fable 5.1: $10 / $50
- GPT-6.1 Sol: $2 / $10 ($0.10 cached input); GPT-6 Astra: $10 / $50; GPT-6 Luna: $0.10 / $0.50
- GPT-6.1 Sol prompts over 272K input tokens bill at 2x input and 1.5x output for the whole request
The agent-team arithmetic matters more than the headline rates. For workloads spawning multiple sub-agents, run Sonnet 5.5 or Haiku 5.5 workers under an Opus 5.5 lead, or Luna workers under a GPT-6.1 Sol lead. A Sonnet 5.5 token costs half an Opus 5.5 token, and a Luna token costs a twentieth of a Sol token. Claude's effort levels (through "max") and GPT-6.1 Sol's low-to-max reasoning effort both let you tune cost against thoroughness per task.
The Configuration Tax: Setup Time Reality
Both tools have converged on features. Codex now has goals, memories, hooks, plugins, and vim mode. Claude Code now has the agent view dashboard, custom themes, effort levels, and /ultrareview. The configuration gap is narrower than in February.
Codex: What Changed Through October 2026
- v0.163.0 (October 15): /config search, steer a running turn with a follow-up, leader key in /keymap, parallel read-only tools, Daybreak on by default
- GPT-6.1 Sol recommended; GPT-5.5 retired for ChatGPT sign-in on October 14; Pro adds a $500 tier
- codex agents dashboard: search, start, open, rename, and stop tasks interactively (v0.149.0, August 20)
- Queued messaging to running sessions (v0.149.0)
- Portable Agent Plugins with local and workspace catalog search (v0.147.0, August 4)
- Automated approvals via the --approve-for-me flag (v0.147.0)
- MCP 2026-07-28 protocol support with paginated discovery (v0.147.0)
- Thread pinning and forking with paginated history (v0.146.0, July 28)
- GPT-5.6 family (Sol recommended); GPT-5.4 retires August 31
- Subagents GA (March 14): manager-worker pattern with a configurable thread cap
- /goal command: persistent multi-day objectives with pause/resume (v0.128.0)
- Memories: cross-session context, git-backed workspace diffs (configurable)
- Vim mode in TUI composer with /vim command (v0.129.0)
- codex remote-control: headless app-server for CI/pipeline integration (v0.130.0)
- Chrome extension with parallel tab support (May 7)
- Mobile support via ChatGPT mobile + Codex App connection (May 14)
- Hooks GA: lifecycle hooks browsable from /hooks (v0.129.0)
- GPT-5.5 model support, GPT-5.4 for Bedrock
- Plugin marketplace with workspace sharing and remote bundles
- ~130,000 GitHub stars, Apache-2.0
Claude Code: What Changed Through October 2026
- Opus 5.5 default on Pro, Max, Team, Enterprise, and the API (v2.1.280); Sonnet 5.5 needs v2.1.284, Haiku 5.5 v2.1.293
- v2.1.302 (October 16): fork subagents on by default in claude -p, the Agent SDK, desktop, and VS Code; CLAUDE_CODE_AUTO_MODE_MODEL; idle compaction toggle
- Opus 5 default (week of July 20): 97.0% SWE-bench Verified on vals.ai, 1M context, fast mode $10/$50
- Cross-session messaging: sessions pass findings to each other (v2.1.220+, early August)
- Auto mode is the default permission mode for new sessions on Pro, Max, and Team (August 14)
- Self-hosted cloud environments in public beta on Team and Enterprise
- Sonnet 5 default on Pro, Team Standard, and Enterprise seats (late June)
- Opus 4.8 default era (May 28): SWE-bench Verified 88.6%, Pro 69.2%, CursorBench 70%
- claude agents dashboard: unified view of all sessions (v2.1.139, May 11)
- /goal command: persistent work until completion condition met (v2.1.139)
- /ultrareview: parallel multi-agent cloud code review (v2.1.111)
- Effort levels: xhigh between high and max (v2.1.111, April 16)
- Auto mode available for Max subscribers without --enable flag
- Custom themes via /theme command (v2.1.118)
- Vim visual mode (v) and visual-line mode (V) (v2.1.118)
- Plugin ecosystem with marketplace, hooks, and MCP tool integration
- Push notifications via Remote Control (v2.1.110)
- PowerShell support on Windows (progressive rollout, v2.1.111)
- ~152,000 GitHub stars, v2.1.303 (October 18, 2026), proprietary
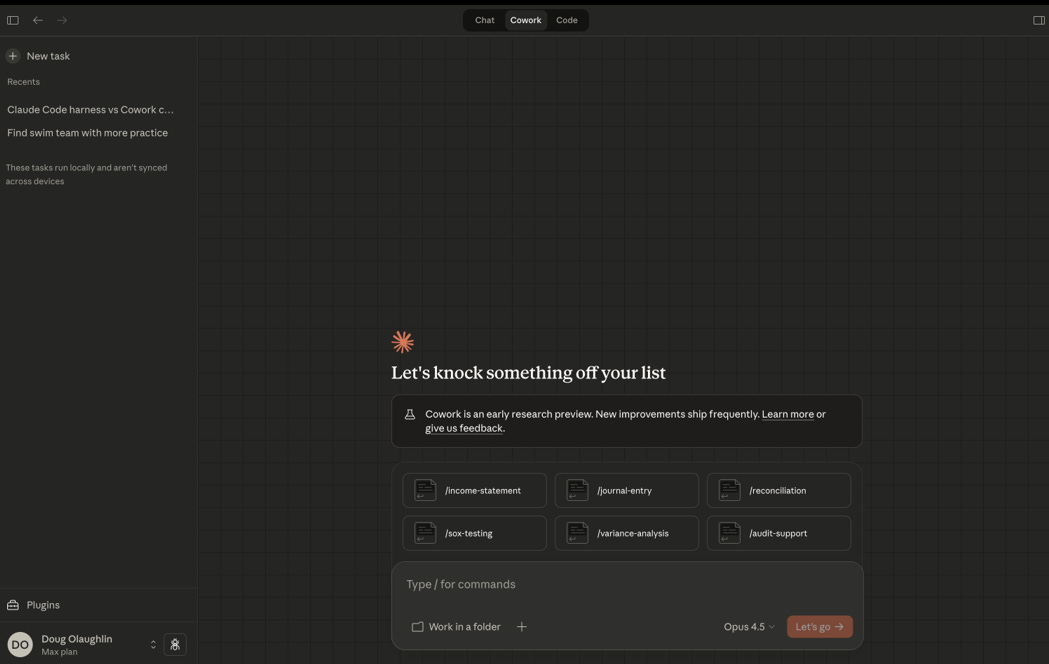
Anthropic's Cowork desktop app for Claude Code. Folder-based project management with task routing. Source: SemiAnalysis.
The configuration gap between these tools has narrowed. Both now support goals, memories, hooks, plugins, vim mode, and remote/headless operation. Codex ships AGENTS.md (similar to CLAUDE.md). The main remaining difference: Claude Code's hooks are more granular (PreToolUse, PostToolUse, PreCompact) while Codex's are lifecycle-scoped.
Claude Code: CLAUDE.md Example
# CLAUDE.md - Project-specific instructions

## Code Style
- Use TypeScript strict mode
- Prefer functional components
- No any types without explicit comment

## Architecture
- All API calls go through /lib/api
- State management via Zustand
- Never modify package.json without asking

## Testing
- Write tests before implementation (TDD)
- Minimum 80% coverage for new code
- Use React Testing Library patterns
With Claude Code, you can completely replace the system prompt. This is useful for creating specialized agents, but it is a time investment that Codex does not require.
Failure Mode Analysis: When Things Go Wrong
Both tools fail. Understanding HOW they fail tells you which failure mode you can tolerate.
Codex Failure Patterns
- Variability: Same prompt produces different results across runs
- Off-plan drift: Ignores instructions when "in the zone"
- Defensive over-engineering: Adds unnecessary error handling
- Style ignorance: Doesn't adapt to codebase patterns
- Context switching: Loses track in complex multi-file edits
- Multi-agent CSV fan-out: No mid-batch error recovery, one failure can stall the pipeline
- Security: zsh sandbox bypass fixed in v0.106.0, but raises questions about sandbox trust model
A "Codex is rapidly degrading" thread gained traction on the OpenAI community forum in spring 2026, with users reporting declining output quality. The GPT-5.6 switch reset much of that conversation, but same-prompt variability remains the most-reported Codex complaint. Worth monitoring if you are evaluating Codex for a long-term workflow.
Claude Code Failure Patterns
- Over-interruption: Asks permission too frequently (mitigated by auto-accept mode)
- Context window issues: Compaction hits after 5-6 prompts
- Limit walls: Stops mid-task when hitting caps
- Eager gap-filling: Makes assumptions without flagging them
- Token bloat: Verbose explanations eat into limits
For context on Claude Code's real-world reliability: Rakuten reported 99.9% numerical accuracy on a 12.5M-line codebase. At that scale, even small failure rates compound. The gap between Codex and Claude on consistency is measurable in production.
"Codex sometimes flags plausible edge-case database query concurrency bugs that I have to manually verify for 30 minutes, only to conclude they're hallucinations." (HN commenter)
The Recovery Question
When Codex fails, you typically need to re-prompt from scratch. When Claude fails, you can often guide it back on track through conversation. This makes Claude failures feel more recoverable, even if they happen more often due to limit issues.
The Context Window Problem: The Hidden Battleground
This battleground closed in 2026. Claude Opus 5.5 reads 1M tokens with 128K max output; GPT-6.1 Sol reads 1,050,000 tokens (922K max input) with 128K output. The differentiation moved from raw size to how each tool manages a long session.
| Aspect | GPT-6.1 Sol / Codex | Claude Opus 5.5 / Claude Code |
|---|---|---|
| Raw context window | 1,050,000 tokens, 128K output | 1M tokens, 128K output |
| Memory management | Diff-based forgetting + Memories MCP | Automatic compaction + auto-memory |
| Large file handling | Smooth up to 2000+ lines | Handles massive files across the full window |
| Multi-agent context | Isolated per agent, configurable thread cap | Shared via team config + task list |
| Long session stability | Excellent with diff-based forgetting | Improved: compaction + /goal for persistent work |
| Effort control | Standard reasoning levels | xhigh effort level (between high/max) |
With raw size tied at 1M, session management is the remaining difference. Codex uses diff-based forgetting plus a Memories MCP server (v0.129.0) that provides structured cross-session context with search, pagination, and line-offset reads. Claude Code's auto-memory and automatic compaction handle long sessions differently: summarizing old context instead of diffing it away. For a deep dive on why context rot degrades agent performance and how context compression techniques like FlashCompact address it, see our analysis.
Where Codex Wins
Faster Terminal Runs
On vals.ai's Terminal-Bench 2.1 run, GPT-6 Astra finishes a test in 4m34s on average against 6m23s for Opus 5.5, at nearly the same score (87.27% vs 87.64%). GPT-6 Sol takes 4m59s. Claude now wins the score; Codex still wins the clock.
Long Autonomous Sessions with Goals
The /goal command (v0.128.0) lets Codex schedule future work and wake up automatically to continue on long-term tasks, potentially across days or weeks. Combined with memories for cross-session context, Codex now handles truly persistent workflows.
Budget-Conscious Teams
ChatGPT Plus ($20) publishes its Codex limits (15-160 GPT-6.1 Sol messages per five hours) and Pro has no five-hour limit. The $8 Go tier, GPT-6 Luna on the Free plan, and Luna at $0.10/$0.50 per M tokens give more price points than Claude's lineup.
Cost Per Resolved Task
On the DeepSWE leaderboard (September 22, 2026), GPT-6 Astra resolves 74% of tasks at $4.43 each and Claude Opus 5 resolves 74% at $11.84. Same resolution rate, 63% less money. For a well-specified ticket queue, that column settles it.
Best For: Spec-Driven Parallel Workflows
If you write detailed specs and want to context-switch while the AI works, Codex is your tool. The Codex App (macOS + Windows), Chrome extension (May 7), and mobile access (May 14) make this workflow available everywhere. Subagents GA means one task can fan out to parallel workers. The codex remote-control command (v0.130.0) enables headless operation for CI/pipeline integration.
Where Claude Code Wins
Benchmark Scores, Every Board
Claude Code with Opus 5.5 leads Terminal-Bench 4.0 at 64.85% against 58.18% for Codex with GPT-6.1 Sol. Opus 5.5 leads SWE-bench Pro at 89.9% (llm-stats), and Opus 5 leads vals.ai SWE-bench Verified at 97.0% against GPT-5.6 Sol's 96.2%. For real-world codebase fixes, Claude has the edge.
Massive Codebase Navigation
Opus 5.5 reads 1M tokens with 128K output, and Agent Teams split a repo-wide change across agents that each keep their own context window and share one task list.
Session Orchestration at Scale
The 'claude agents' dashboard shows all running, blocked, and completed sessions; cross-session messaging (v2.1.220+, August 2026) lets sessions hand findings to each other; dynamic workflows script dozens to hundreds of subagents. Combined with /goal and /ultrareview, Claude Code's session management is more sophisticated.
Custom Automation via Hooks
Claude Code's hooks are more granular: PreToolUse, PostToolUse, PreCompact, PostToolUseFailure with duration_ms, continueOnBlock, and MCP tool invocation. Build CI-like pipelines around your agent workflows with fine-grained lifecycle control.
Best For: Multi-Agent Orchestration
If you want to architect a solution and let a team of agents execute it in parallel, with dependency tracking, inter-agent messaging, and shared task lists, Claude Code's Agent Teams remain the strongest option. 16 Claude agents wrote a 100,000-line C compiler in Rust that builds Linux 6.9, passing 99% of the GCC torture test suite, over about 2,000 Claude Code sessions and $20,000 in API costs. Opus 5.5 raised the per-agent ceiling again: 89.9% on SWE-bench Pro against Opus 4.8's 69.2%, at a lower price ($4/$20 vs $5/$25).
"For production coding, I create fairly strict plans. Codex goes off plan most of the time. Claude follows them.",HN commenter
Hybrid Workflow: Using Both
Power users figured this out early: these tools complement each other. The optimal workflow is not choosing one. It is knowing when to switch.
The Optimal Hybrid Flow
- Prototype with Codex: Fast iteration, explore multiple approaches
- Review with Claude: Code review, catch edge cases Codex missed
- Refactor with Claude: Complex architectural changes with deterministic outputs
- Final polish with Codex: Quick fixes and formatting
Power User Hybrid Workflow (October 2026)
# 1. Scaffold with Codex subagents in cloud sandbox
$ codex "Implement user authentication with JWT, following patterns in /lib/auth"
# Manager spawns explorer + worker agents in parallel sandboxes
# /goal keeps the task alive across sessions if needed

# 2. Orchestrate review + hardening with Claude Agent Teams
$ claude "Review the auth implementation. Spawn a security reviewer agent
         and a test writer agent. Security reviewer checks for OWASP top 10.
         Test writer creates integration tests. Block merge until both pass."
# claude agents dashboard shows all agents' status
# /ultrareview runs parallel multi-agent cloud code review

# 3. Quick fix with Codex
$ codex "Fix these 3 security issues: [paste Claude's findings]"
# Done in 2 minutes, cloud sandbox, no context pollutionSeveral developers report using Codex specifically to review Claude's work. "I use Codex for review tasks. When working on something complex, I frequently ask Codex to review Claude's work, and it does a good job catching mistakes."
Decision Framework: Pick Your Tool in 30 Seconds
| Your Situation | Best Choice | Why |
|---|---|---|
| Multi-agent orchestration | Claude Code | Agent Teams with task deps + messaging + agent view |
| Parallel sandbox execution | Codex | Subagents GA with a configurable thread cap |
| Budget: $20/month | Codex | More sessions per dollar on ChatGPT Plus |
| SWE-bench accuracy | Claude Code | 89.9% SWE-bench Pro (Opus 5.5); 97.0% Verified (Opus 5) |
| Cheapest resolved ticket | Codex | DeepSWE: $4.43/task (GPT-6 Astra) vs $11.84 (Opus 5) |
| Terminal-heavy workflows | Claude Code | 64.85% vs 58.18% Terminal-Bench 4.0 (tbench.ai) |
| Large codebase refactoring | Claude Code | 1M context + agent teams for divide-and-conquer |
| Persistent multi-day tasks | Codex | /goal with auto-wakeup, memories for cross-session context |
| Custom automation | Claude Code | Granular hooks (PreToolUse, PostToolUse, PreCompact) |
| Want open-source CLI | Codex | Apache-2.0, Rust-native, ~130K stars |
| Max context window | Tie | Both read about 1M tokens with 128K output |
What We Route Where
We run both tools daily against this codebase and our serving infrastructure, so here is the routing we actually use rather than a hypothetical. Well-specified tickets and CI scripting go to Codex: the spec is written, the completion criteria are clear, and $4.43 per resolved task beats $11.84 when the two models resolve at the same rate. Repo-wide refactors and "figure out why this is broken" investigations go to Claude Code, where an Opus 5.5 lead with Sonnet 5.5 workers fans out across the codebase and the agents hand findings to each other instead of us re-explaining context. Code review runs cross-tool: Codex reviews Claude's diffs and catches a different class of mistakes than the author model does. The one pattern we dropped: using either tool's $100 tier before maxing out both $20 plans.
Frequently Asked Questions
Is Codex or Claude Code better for coding in 2026?
As of October 19, 2026, Claude Code leads on accuracy and Codex leads on price. Claude Code defaults to Claude Opus 5.5 ($4/$20 per million tokens) and scores 64.85% on the official Terminal-Bench 4.0 leaderboard, against 58.18% for Codex with GPT-6.1 Sol ($2/$10). On vals.ai Terminal-Bench 2.1, Opus 5.5 posts 87.64% and GPT-6 Astra 87.27%. Codex wins cost per resolved task: GPT-6 Astra resolves 74% of DeepSWE tasks at $4.43 each, the same rate Claude Opus 5 reaches at $11.84. Codex Pro plans ($100, $200, $500) have no five-hour limit; Claude Max is $100 or $200. Subagents: Claude Code Agent Teams share a task list and message each other; Codex spawns parallel subagents with a configurable thread cap.
Claude vs Codex: what are people actually comparing?
Claude is Anthropic's model family; Claude Code is the coding agent that runs those models in your terminal, IDE, or cloud. Codex is OpenAI's coding agent, which runs the GPT-6 family (GPT-6.1 Sol recommended, GPT-6 Astra for the hardest work, GPT-6 Luna for repeatable tasks). So 'claude vs codex' and 'claude codex' searches are really Claude Code vs Codex. The model matchup underneath is Claude Opus 5.5 vs GPT-6.1 Sol: Opus 5.5 scores 64.85% on Terminal-Bench 4.0 in Claude Code against 58.18% for GPT-6.1 Sol in Codex, and GPT-6.1 Sol costs half as much per token ($2/$10 vs $4/$20).
What are Claude Code Agent Teams?
Agent Teams let you spin up multiple sub-agents that work in parallel on different parts of a task. Each agent gets its own context window, they share a task list with dependency tracking, and they message each other. The 'claude agents' dashboard (v2.1.139) manages all sessions, sessions can message each other directly (v2.1.220+), and since v2.1.302 (October 16, 2026) fork subagents are on by default in claude -p, the Agent SDK, the desktop app, and VS Code. The '/goal' command keeps an agent working until a completion condition is met.
What are Codex subagents?
Codex shipped subagents to GA on March 14, 2026. The main agent spawns explorer, worker, or custom agents in parallel and collects their results. The cap on concurrent agent threads is configurable with agents.max_concurrent_threads_per_session (agents.max_threads still works as a legacy alias); when you leave it unset, Codex picks the default. Ultra mode uses subagents on its own for large tasks, and v0.163.0 also runs independent read-only tools in parallel.
Which has better usage limits: Codex or Claude Code?
Codex publishes per-model ranges for local messages per five-hour window. ChatGPT Plus ($20) gets about 15-160 GPT-6.1 Sol messages, 5-45 GPT-6 Astra, and 350-3,000 GPT-6 Luna per window, and weekly limits may also apply. Pro plans at $100, $200, and $500 currently have no five-hour limit. Anthropic sells Pro ($20, or $17/month billed annually) and Max at $100 (5x Pro usage) or $200 (20x), shared between the Claude apps and Claude Code, and publishes no message counts. Both sell extra usage when you hit a limit. Subagent workflows multiply consumption because each agent uses its own context window.
Can I use both Codex and Claude Code together?
Yes, and the hybrid workflow is increasingly common, including on our team. Use Codex for rapid prototyping and subagent-parallel implementation in cloud sandboxes, then use Claude Code's Agent Teams for code review (/ultrareview), security auditing, and complex refactoring with coordinated agents. The two $20 plans together cost less than either $100 tier.
Can I use Codex or Claude Code for free?
Partly. The Codex CLI itself is free and open source, but it needs a ChatGPT plan or an OpenAI API key to run models. The ChatGPT Free plan gets GPT-6 Luna at Standard speed in the desktop app, subject to rollout; Go is $8/month and Plus is $20. With an API key you pay API rates, for example $2/$10 per million tokens on GPT-6.1 Sol. Claude Code has no free tier: it starts with Claude Pro at $20/month.
Which is more open source?
Codex CLI is open source under Apache-2.0 (Rust-native, about 130,000 GitHub stars; v0.163.0 shipped October 15, 2026). Claude Code is proprietary but publicly available (about 152,000 stars; v2.1.303 shipped October 18, 2026, with 2.1.292 on the stable channel). Neither tool's underlying models are open source. Both ship several releases per week and have plugin ecosystems.
WarpGrep v2 Boosts Any Coding Agent on SWE-bench Pro
WarpGrep v2 adds 2-3 points on SWE-bench Pro to every model tested: Opus 4.6 from 55.4% to 57.5%, Codex from 57.0% to 59.1%. It works as an MCP server inside Claude Code, Codex, Cursor, and any tool that supports MCP. Better search = better context = better code.
Sources
- Claude Code Changelog (v2.1.303, October 18, 2026)
- Claude Code Model Configuration (Opus 5.5 default)
- OpenAI Codex CLI Releases (v0.163.0, October 15, 2026)
- OpenAI: Codex Models (GPT-6.1 Sol, GPT-6 Astra, GPT-6 Luna; GPT-5.5 retirement)
- OpenAI: Codex Pricing and Per-Plan Limits
- Anthropic: Models Overview and Pricing
- Terminal-Bench 4.0 Leaderboard (tbench.ai)
- vals.ai Terminal-Bench 2.1 Leaderboard (as of September 28, 2026)
- vals.ai SWE-bench Verified Leaderboard (as of September 1, 2026)
- llm-stats SWE-Bench Pro Leaderboard
- DeepSWE v1.1 Leaderboard (updated September 22, 2026)
- SemiAnalysis: Claude Code is the Inflection Point (Feb 5, 2026)
- Anthropic Engineering: Building a C Compiler with Claude Agents
- SWE-bench Pro Leaderboard: Every Model Score
- Claude Code vs Cursor: Full Comparison